Physics-Informed Neural Networks vs Traditional Simulation
Physics-informed neural networks embed governing equations into training, cutting simulation cost and speeding up digital twins vs traditional solvers.
• 12 min read
Read Article
Comprehensive deep learning guides covering neural networks, transformers, and advanced architectures to help you build and deploy AI systems.
Physics-informed neural networks embed governing equations into training, cutting simulation cost and speeding up digital twins vs traditional solvers.
Federated learning trains models on-device while centralized ML pools data in one place. Compare privacy, cost, and accuracy to choose the right approach.
Model quantization and knowledge distillation both shrink AI models to cut inference costs. Compare mechanics, accuracy tradeoffs, and when each wins.
GANs and autoencoders both flag anomalies, but the mechanics differ. Compare architectures, accuracy, and cost to pick the right model for fraud detection.
Compare RNN and Transformer architectures for sequence data — performance, training cost, latency, and when each still makes sense for business AI in 2026.
MoE models activate a fraction of parameters per token; dense models use them all. Compare architecture, training cost, and which one fits your AI stack.
Learn how to plot a neural network's classification boundary step by step with scikit-learn, Matplotlib, and TensorFlow Playground to catch overfitting early.
Learn what an AI agent is, how it differs from chatbots and RPA, and get a five-step framework for evaluating and deploying AI agents in your business.
RLHF (reinforcement learning from human feedback) aligns LLM outputs with human preferences. Learn the three-stage pipeline, costs, and business impact.
Multi-head attention runs parallel heads so transformers capture syntax, semantics, and context. Learn how it works and why head count drives serving cost.
Diffusion models power Stable Diffusion, DALL-E 3, and Sora. Learn how they denoise data step-by-step, why they beat GANs, and how businesses deploy them.
RAG (retrieval-augmented generation) grounds LLM responses in your own documents, cutting hallucinations and enabling current, verifiable business AI answers.
Discover what mixture of experts models are, how they revolutionize AI efficiency, and why they're transforming machine learning in 2026. Complete guide with examples.
Layer normalization stabilizes transformer and LLM training by normalizing across features. Learn how it works, pre-LN vs post-LN, RMSNorm, and when to use it.
Discover how diffusion models revolutionize AI image generation. Learn the technology behind DALL-E, Midjourney, and Stable Diffusion in our comprehensive 2026 guide.
Learn proven strategies to reduce AI inference latency in 2026. Discover optimization techniques, hardware acceleration, and best practices for faster AI response times.
Master transfer learning in deep learning with our comprehensive 2026 guide. Learn techniques, applications, and practical implementation strategies for AI success.
Discover distributed AI training benefits including faster model training, improved scalability, and cost efficiency. Learn implementation strategies for 2026.
TensorFlow Playground lets you visualize neural networks live in your browser. Learn how to use it, which hyperparameters matter, and when to outgrow it.
What is a vision transformer? A clear guide to ViT architecture, how it compares to CNNs, top variants, and when to use ViT in production business systems.
What is the T5 model in NLP? A practical guide to Google's text-to-text transformer architecture, key variants, and business applications for AI teams in 2026.
What is a convolutional neural network? A clear guide to CNN architecture, convolutional layers, business use cases, and how CNNs differ from MLPs and
Batch normalization stabilizes deep network training by normalizing layer inputs. Learn the mechanics, placement rules, variants, and production ML guidance.
Learn what the delta rule is in neural networks: the error-driven weight update formula first published by Widrow & Hoff in 1960, with worked examples.
Learn how feedforward neural networks work, from single-layer perceptrons to deep MLPs. Covers architecture, backpropagation, and key business applications.
Dropout randomly deactivates neurons during training to prevent overfitting. Learn how deep learning dropout works, variants, and the right rate for your model.
Word embedding converts text into numerical vectors that capture semantic meaning. Learn how Word2Vec, GloVe, and BERT embeddings work and where to use each.
Learn how convolutional neural networks classify images, compare top CNN architectures, and choose the right implementation approach for your business.
Backpropagation trains neural networks by computing error gradients layer by layer. Learn how it works and what it means for AI training costs and deployment.
Fine-tuning adapts a pre-trained deep learning model for your specific task with far less data. Learn how it works, when to use it, and real business ROI.
What is positional encoding in transformers? Learn sinusoidal PE, RoPE, and ALiBi — how each works and why PE determines a model's usable context window.
BERT is Google's 2018 NLP model that changed language understanding with bidirectional pre-training. Learn how it works and where it beats GPT for business.
Yes — every LLM is a transformer-based neural network. Discover how LLM architecture differs from traditional nets and which model type fits your use case.
The attention mechanism in deep learning is the engine behind ChatGPT, BERT, and every modern transformer. Learn how QKV scoring enables AI to focus on context.
ChatGPT is a decoder-only transformer neural network. Learn how LLMs are trained, what sets them apart from earlier AI, and what this means for your strategy.
Learn how deep learning models like LSTM and Temporal Fusion Transformers outperform ARIMA for demand forecasting, financial prediction, and operations.
Master how to determine neural network input layers: feature mapping, normalization, and architecture choices for building accurate deep learning models.
Deep graph learning uses graph neural networks to find patterns in connected data. Learn how GNNs work, their key business applications, and how to get started.
Activation functions control how neural networks learn. This guide covers ReLU, sigmoid, tanh, softmax, and how to choose the right function for your AI model.
Learn how gradient descent powers deep learning model training. Discover optimizer types, learning rate strategies, and practical tips for your AI projects.
A step-by-step guide to building neural networks — architecture design, training techniques, evaluation metrics, and deployment strategies for your team.
Learn how deep learning works, from neural network training to business applications in vision, NLP, and automation. A practical guide for decision-makers.
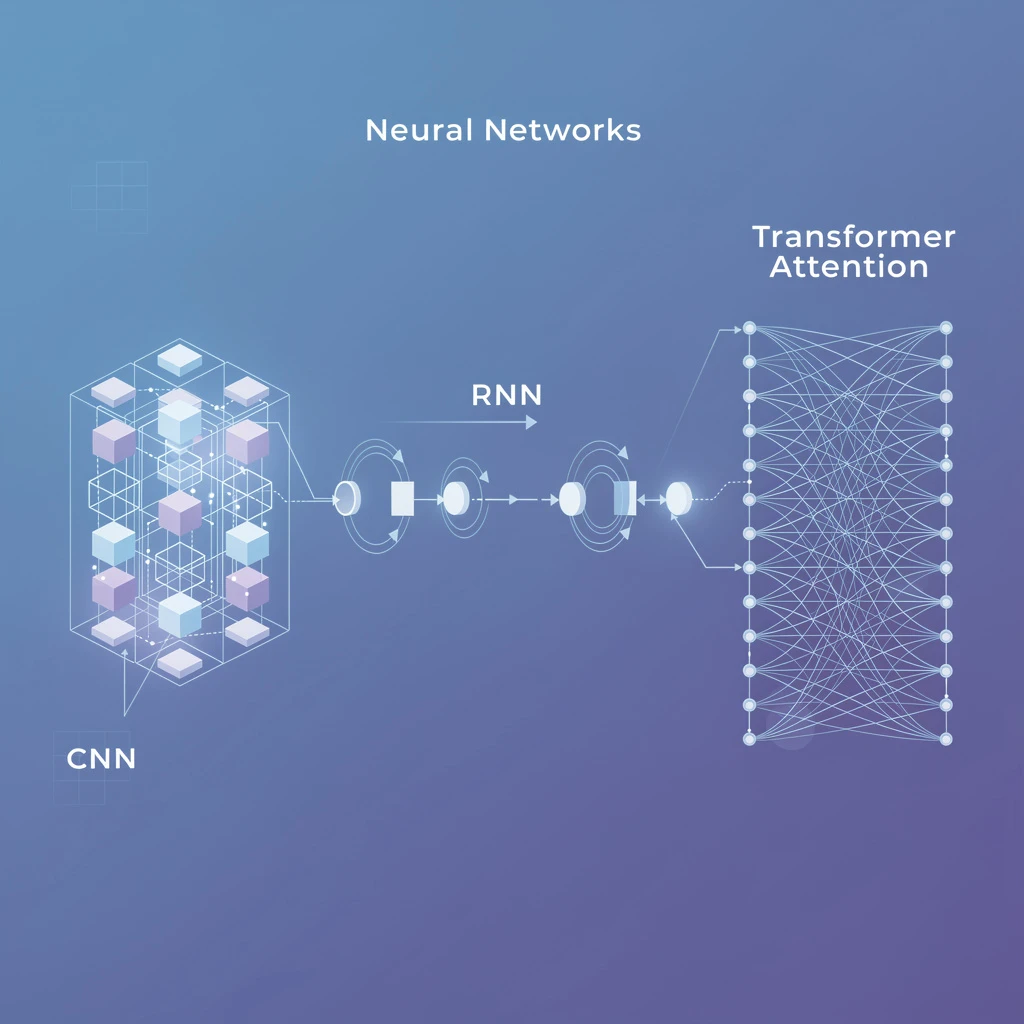
Discover the main types of neural networks—CNNs, RNNs, LSTMs, transformers, and GANs—with practical use cases to help you choose the right architecture.
Master transfer learning in machine learning. Learn how pre-trained models save time, reduce data requirements, and deliver 10x faster results for your...
Learn what a transformer is in machine learning, how the attention mechanism works, and why transformer models like GPT and BERT power modern AI applications.